Python, как подсчитать кол-во итераций в цикле for
Изучаю сортировку пузырьком для списков. Подскажите, как посчитать количество итераций в цикле for:
Дизайн сайта / логотип © 2023 Stack Exchange Inc; пользовательские материалы лицензированы в соответствии с CC BY-SA . rev 2023.9.7.43618
Нажимая «Принять все файлы cookie» вы соглашаетесь, что Stack Exchange может хранить файлы cookie на вашем устройстве и раскрывать информацию в соответствии с нашей Политикой в отношении файлов cookie.
Подсчёт количества итераций в Python: обзор нескольких способов решения задачи
Подсчёт количества итераций является частой задачей в программировании на языке Python. Например, можно использовать это для оптимизации кода или измерения производительности. В этой статье мы рассмотрим несколько способов подсчёта количества итераций в Python.
1. Цикл for
Цикл for в Python осуществляет итерацию по объекту, например, по списку или строке. Чтобы подсчитать количество итераций с помощью цикла for , используйте функцию enumerate() . Она возвращает пару значений – индекс элемента и сам элемент из последовательности. Затем мы можем использовать этот индекс для подсчёта количества итераций.
Чтобы получить количество итераций, просто используйте функцию len() :
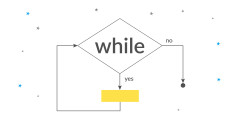
2. Цикл while
Цикл while в Python повторяет выполнение блока кода до тех пор, пока верно условие. Можно использовать цикл while для подсчёта количества итераций, если вы знаете условие, при котором цикл должен остановиться.
3. Функция range()
Функция range() в Python создаёт последовательность чисел. Эту последовательность можно использовать в циклах for и while для подсчёта количества итераций.
4. Итераторы
Итераторы в Python – это объекты, которые возвращают последовательность значений. Функция iter() создаёт итератор из объекта, который можно перебирать. Итераторы можно использовать для подсчёта количества итераций.
Заключение
В этой статье мы рассмотрели несколько способов подсчёта количества итераций в Python. Выбор конкретного способа зависит от вашей задачи и предпочтений. Цикл for и функция range() самые распространённые способы, но итераторы могут быть полезными в определённых ситуациях.
itertools — Functions creating iterators for efficient looping
This module implements a number of iterator building blocks inspired by constructs from APL, Haskell, and SML. Each has been recast in a form suitable for Python.
The module standardizes a core set of fast, memory efficient tools that are useful by themselves or in combination. Together, they form an “iterator algebra” making it possible to construct specialized tools succinctly and efficiently in pure Python.
For instance, SML provides a tabulation tool: tabulate(f) which produces a sequence f(0), f(1), . . The same effect can be achieved in Python by combining map() and count() to form map(f, count()) .
These tools and their built-in counterparts also work well with the high-speed functions in the operator module. For example, the multiplication operator can be mapped across two vectors to form an efficient dot-product: sum(starmap(operator.mul, zip(vec1, vec2, strict=True))) .
Infinite iterators:
start, start+step, start+2*step, …
count(10) —> 10 11 12 13 14 .
p0, p1, … plast, p0, p1, …
cycle(‘ABCD’) —> A B C D A B C D .
elem, elem, elem, … endlessly or up to n times
repeat(10, 3) —> 10 10 10
Iterators terminating on the shortest input sequence:
accumulate([1,2,3,4,5]) —> 1 3 6 10 15
p0, p1, … plast, q0, q1, …
chain(‘ABC’, ‘DEF’) —> A B C D E F
p0, p1, … plast, q0, q1, …
chain.from_iterable([‘ABC’, ‘DEF’]) —> A B C D E F
(d[0] if s[0]), (d[1] if s[1]), …
compress(‘ABCDEF’, [1,0,1,0,1,1]) —> A C E F
seq[n], seq[n+1], starting when pred fails
dropwhile(lambda x: x<5, [1,4,6,4,1]) —> 6 4 1
elements of seq where pred(elem) is false
filterfalse(lambda x: x%2, range(10)) —> 0 2 4 6 8
sub-iterators grouped by value of key(v)
seq, [start,] stop [, step]
elements from seq[start:stop:step]
islice(‘ABCDEFG’, 2, None) —> C D E F G
pairwise(‘ABCDEFG’) —> AB BC CD DE EF FG
starmap(pow, [(2,5), (3,2), (10,3)]) —> 32 9 1000
seq[0], seq[1], until pred fails
takewhile(lambda x: x<5, [1,4,6,4,1]) —> 1 4
it1, it2, … itn splits one iterator into n
zip_longest(‘ABCD’, ‘xy’, fillvalue=’-‘) —> Ax By C- D-
Combinatoric iterators:
cartesian product, equivalent to a nested for-loop
r-length tuples, all possible orderings, no repeated elements
r-length tuples, in sorted order, no repeated elements
r-length tuples, in sorted order, with repeated elements
AA AB AC AD BA BB BC BD CA CB CC CD DA DB DC DD
AB AC AD BA BC BD CA CB CD DA DB DC
AB AC AD BC BD CD
AA AB AC AD BB BC BD CC CD DD
Itertool functions
The following module functions all construct and return iterators. Some provide streams of infinite length, so they should only be accessed by functions or loops that truncate the stream.
itertools. accumulate ( iterable [ , func , * , initial=None ] ) 
Make an iterator that returns accumulated sums, or accumulated results of other binary functions (specified via the optional func argument).
If func is supplied, it should be a function of two arguments. Elements of the input iterable may be any type that can be accepted as arguments to func. (For example, with the default operation of addition, elements may be any addable type including Decimal or Fraction .)
Usually, the number of elements output matches the input iterable. However, if the keyword argument initial is provided, the accumulation leads off with the initial value so that the output has one more element than the input iterable.
Roughly equivalent to:
There are a number of uses for the func argument. It can be set to min() for a running minimum, max() for a running maximum, or operator.mul() for a running product. Amortization tables can be built by accumulating interest and applying payments:
See functools.reduce() for a similar function that returns only the final accumulated value.
New in version 3.2.
Changed in version 3.3: Added the optional func parameter.
Changed in version 3.8: Added the optional initial parameter.
Make an iterator that returns elements from the first iterable until it is exhausted, then proceeds to the next iterable, until all of the iterables are exhausted. Used for treating consecutive sequences as a single sequence. Roughly equivalent to:
Alternate constructor for chain() . Gets chained inputs from a single iterable argument that is evaluated lazily. Roughly equivalent to:
Return r length subsequences of elements from the input iterable.
The combination tuples are emitted in lexicographic ordering according to the order of the input iterable. So, if the input iterable is sorted, the output tuples will be produced in sorted order.
Elements are treated as unique based on their position, not on their value. So if the input elements are unique, there will be no repeated values in each combination.
Roughly equivalent to:
The code for combinations() can be also expressed as a subsequence of permutations() after filtering entries where the elements are not in sorted order (according to their position in the input pool):
The number of items returned is n! / r! / (n-r)! when 0 <= r <= n or zero when r > n .
itertools. combinations_with_replacement ( iterable , r ) 
Return r length subsequences of elements from the input iterable allowing individual elements to be repeated more than once.
The combination tuples are emitted in lexicographic ordering according to the order of the input iterable. So, if the input iterable is sorted, the output tuples will be produced in sorted order.
Elements are treated as unique based on their position, not on their value. So if the input elements are unique, the generated combinations will also be unique.
Roughly equivalent to:
The code for combinations_with_replacement() can be also expressed as a subsequence of product() after filtering entries where the elements are not in sorted order (according to their position in the input pool):
The number of items returned is (n+r-1)! / r! / (n-1)! when n > 0 .
New in version 3.1.
Make an iterator that filters elements from data returning only those that have a corresponding element in selectors that evaluates to True . Stops when either the data or selectors iterables has been exhausted. Roughly equivalent to:
New in version 3.1.
Make an iterator that returns evenly spaced values starting with number start. Often used as an argument to map() to generate consecutive data points. Also, used with zip() to add sequence numbers. Roughly equivalent to:
When counting with floating point numbers, better accuracy can sometimes be achieved by substituting multiplicative code such as: (start + step * i for i in count()) .
Changed in version 3.1: Added step argument and allowed non-integer arguments.
Make an iterator returning elements from the iterable and saving a copy of each. When the iterable is exhausted, return elements from the saved copy. Repeats indefinitely. Roughly equivalent to:
Note, this member of the toolkit may require significant auxiliary storage (depending on the length of the iterable).
itertools. dropwhile ( predicate , iterable ) 
Make an iterator that drops elements from the iterable as long as the predicate is true; afterwards, returns every element. Note, the iterator does not produce any output until the predicate first becomes false, so it may have a lengthy start-up time. Roughly equivalent to:
Make an iterator that filters elements from iterable returning only those for which the predicate is false. If predicate is None , return the items that are false. Roughly equivalent to:
Make an iterator that returns consecutive keys and groups from the iterable. The key is a function computing a key value for each element. If not specified or is None , key defaults to an identity function and returns the element unchanged. Generally, the iterable needs to already be sorted on the same key function.
The operation of groupby() is similar to the uniq filter in Unix. It generates a break or new group every time the value of the key function changes (which is why it is usually necessary to have sorted the data using the same key function). That behavior differs from SQL’s GROUP BY which aggregates common elements regardless of their input order.
The returned group is itself an iterator that shares the underlying iterable with groupby() . Because the source is shared, when the groupby() object is advanced, the previous group is no longer visible. So, if that data is needed later, it should be stored as a list:
groupby() is roughly equivalent to:
Make an iterator that returns selected elements from the iterable. If start is non-zero, then elements from the iterable are skipped until start is reached. Afterward, elements are returned consecutively unless step is set higher than one which results in items being skipped. If stop is None , then iteration continues until the iterator is exhausted, if at all; otherwise, it stops at the specified position.
If start is None , then iteration starts at zero. If step is None , then the step defaults to one.
Unlike regular slicing, islice() does not support negative values for start, stop, or step. Can be used to extract related fields from data where the internal structure has been flattened (for example, a multi-line report may list a name field on every third line).
Roughly equivalent to:
Return successive overlapping pairs taken from the input iterable.
The number of 2-tuples in the output iterator will be one fewer than the number of inputs. It will be empty if the input iterable has fewer than two values.
Roughly equivalent to:
New in version 3.10.
Return successive r length permutations of elements in the iterable.
If r is not specified or is None , then r defaults to the length of the iterable and all possible full-length permutations are generated.
The permutation tuples are emitted in lexicographic order according to the order of the input iterable. So, if the input iterable is sorted, the output tuples will be produced in sorted order.
Elements are treated as unique based on their position, not on their value. So if the input elements are unique, there will be no repeated values within a permutation.
Roughly equivalent to:
The code for permutations() can be also expressed as a subsequence of product() , filtered to exclude entries with repeated elements (those from the same position in the input pool):
The number of items returned is n! / (n-r)! when 0 <= r <= n or zero when r > n .
itertools. product ( * iterables , repeat = 1 ) 
Cartesian product of input iterables.
Roughly equivalent to nested for-loops in a generator expression. For example, product(A, B) returns the same as ((x,y) for x in A for y in B) .
The nested loops cycle like an odometer with the rightmost element advancing on every iteration. This pattern creates a lexicographic ordering so that if the input’s iterables are sorted, the product tuples are emitted in sorted order.
To compute the product of an iterable with itself, specify the number of repetitions with the optional repeat keyword argument. For example, product(A, repeat=4) means the same as product(A, A, A, A) .
This function is roughly equivalent to the following code, except that the actual implementation does not build up intermediate results in memory:
Before product() runs, it completely consumes the input iterables, keeping pools of values in memory to generate the products. Accordingly, it is only useful with finite inputs.
itertools. repeat ( object [ , times ] ) 
Make an iterator that returns object over and over again. Runs indefinitely unless the times argument is specified.
Roughly equivalent to:
A common use for repeat is to supply a stream of constant values to map or zip:
Make an iterator that computes the function using arguments obtained from the iterable. Used instead of map() when argument parameters are already grouped in tuples from a single iterable (when the data has been “pre-zipped”).
The difference between map() and starmap() parallels the distinction between function(a,b) and function(*c) . Roughly equivalent to:
Make an iterator that returns elements from the iterable as long as the predicate is true. Roughly equivalent to:
Return n independent iterators from a single iterable.
The following Python code helps explain what tee does (although the actual implementation is more complex and uses only a single underlying FIFO queue):
Once a tee() has been created, the original iterable should not be used anywhere else; otherwise, the iterable could get advanced without the tee objects being informed.
tee iterators are not threadsafe. A RuntimeError may be raised when using simultaneously iterators returned by the same tee() call, even if the original iterable is threadsafe.
This itertool may require significant auxiliary storage (depending on how much temporary data needs to be stored). In general, if one iterator uses most or all of the data before another iterator starts, it is faster to use list() instead of tee() .
itertools. zip_longest ( * iterables , fillvalue = None ) 
Make an iterator that aggregates elements from each of the iterables. If the iterables are of uneven length, missing values are filled-in with fillvalue. Iteration continues until the longest iterable is exhausted. Roughly equivalent to:
If one of the iterables is potentially infinite, then the zip_longest() function should be wrapped with something that limits the number of calls (for example islice() or takewhile() ). If not specified, fillvalue defaults to None .
Itertools Recipes
This section shows recipes for creating an extended toolset using the existing itertools as building blocks.
The primary purpose of the itertools recipes is educational. The recipes show various ways of thinking about individual tools — for example, that chain.from_iterable is related to the concept of flattening. The recipes also give ideas about ways that the tools can be combined — for example, how compress() and range() can work together. The recipes also show patterns for using itertools with the operator and collections modules as well as with the built-in itertools such as map() , filter() , reversed() , and enumerate() .
A secondary purpose of the recipes is to serve as an incubator. The accumulate() , compress() , and pairwise() itertools started out as recipes. Currently, the iter_index() recipe is being tested to see whether it proves its worth.
Substantially all of these recipes and many, many others can be installed from the more-itertools project found on the Python Package Index:
Many of the recipes offer the same high performance as the underlying toolset. Superior memory performance is kept by processing elements one at a time rather than bringing the whole iterable into memory all at once. Code volume is kept small by linking the tools together in a functional style which helps eliminate temporary variables. High speed is retained by preferring “vectorized” building blocks over the use of for-loops and generator s which incur interpreter overhead.
Как посчитать количество итераций в цикле питон
while цикл повторяет последовательность действий много раз, пока какое-то условие не достигнет False . Условие задается перед телом цикла и проверяется перед каждым исполнением тела цикла. Как правило, в while используется цикл , когда невозможно определить точное число итераций цикла заранее.
Синтаксис в while цикл в простейшем случае выглядит следующим образом :
Сначала Python проверяет условие. Если это значение False, то цикл завершается и управление передается следующему оператору после в while тело цикла. Если условие истинно, то тело цикла выполняется, а затем условие снова проверяется. Это продолжается, пока условие равно True. Когда условие становится False, цикл завершается и управление передается следующему оператору после цикла.
Например, следующий фрагмент программы печатает квадраты всех целых чисел от 1 до 10. Здесь можно заменить цикл «while» на цикл for . in range(. ) :
В этом примере переменная i внутри цикла выполняет итерацию от 1 до 10. Такая переменная, значение которой изменяется с каждой новой итерацией цикла, называется счетчиком. Обратите внимание, что после выполнения этого фрагмента значение переменной i определено и равно 11 , потому что, когда i == 11 условие i <= 10 является False в первый раз.
Вот другой пример использование в while цикла , чтобы определить количество цифр целого числа n :
На каждой итерации мы сокращаем последнюю цифру числа, используя целочисленное деление на 10 ( n //= 10 ). В переменной length мы подсчитываем, сколько раз мы это делали.
В Python есть еще один, более простой способ решить эту проблему: .
2. Поток управления контуром: else
Можно написать оператор else: после тела цикла, который выполняется один раз после окончания цикла:
На первый взгляд это утверждение, похоже, не имеет смысла, потому else: тело else: statement можно просто поместить после окончания цикла. «else» после цикла имеет смысл только при использовании в сочетании с break . Если во время выполнения цикла интерпретатор Python обнаруживает break , он немедленно останавливает выполнение цикла и выходит из него. В этом случае ветка else: не выполняется. Таким образом, break используется для прерывания выполнения цикла в середине любой итерации.
Вот пример, похожий на Black Jack: программа, которая считывает числа и суммирует их до тех пор, пока общая сумма не станет больше или равна 21. Входная последовательность заканчивается на 0, чтобы программа могла остановиться, даже если общая сумма всех чисел равна менее 21.
Посмотрим, как он ведет себя на разных входах.
Версия 1. После проверки условия цикл завершается нормально, поэтому выполняется ветка else.
Версия 2. Цикл прерывается break , поэтому ветвь «else» пропускается.
Филиал «Else» также может использоваться с циклом «for». Давайте рассмотрим пример, когда программа считывает 5 целых чисел, но останавливается вправо, когда выполняется первое отрицательное целое число.
Версия 1. Цикл завершается нормально, поэтому выполняется ветка «else».
Версия 2. Цикл прерван, поэтому ветка «else» не выполняется.
3. Поток управления контуром: продолжить
Другая инструкция, используемая для управления выполнением цикла, continue . Если интерпретатор Python встречает по- continue где — то в середине итерации цикла, он пропускает все оставшиеся инструкции и переходит к следующей итерации.
Если break и continue помещаются внутри нескольких вложенных циклов, они влияют только на выполнение самого внутреннего. Давайте посмотрим на довольно глупый пример, чтобы продемонстрировать это:
Инструкции break и continue , если вы можете реализовать свою идею без их использования. Вот типичный пример плохого использования break : этот код подсчитывает количество цифр в целых числах.
Это чище и легче читать, чтобы переписать этот цикл со значимым условием цикла:
4. Множественное присвоение
В Python для одного оператора присваивания можно изменить значение нескольких переменных. Посмотрим:
Эффект, продемонстрированный выше, может быть записан как:
Разница между двумя версиями заключается в том, что несколько присваиваний одновременно меняют значения двух переменных.
Множественное назначение полезно, когда вам нужно обменивать значения двух переменных. На старых языках программирования без поддержки множественного назначения это можно сделать с помощью вспомогательной переменной:
В Python один и тот же своп можно записать в одну строку:
Левая часть «=» должна иметь список имен переменных, разделенных запятыми. Правой частью могут быть любые выражения, разделенные запятыми. Левая и правая части должны иметь одинаковую длину.
Цикл "for" в Python — универсальная управляющая конструкция
Ц иклы являются мощнейшим инструментом, предоставляемым высокоуровневыми языками программирования. Эти управляющие конструкции позволяют многократно выполнять требуемую последовательность инструкций. Циклы в языке Python представлены двумя основными конструкциями: while и for .
Применение циклов
Концепция циклов — это не просто очередная абстрактная выдумка программистов. Повторяющиеся раз за разом операции окружают нас и в реальной жизни:
— всё это циклы, и представить нормальную жизнь без них попросту невозможно.
Впрочем, то же касается и программирования. Представьте, что вам нужно последовательно напечатать числа от 1 до 9999999999. В отсутствии циклов, эту задачу пришлось бы выполнять ручками, что потребовало бы колоссального количества кода и огромных временных затрат:
print(1) print(2) print(3) # . # 9999999995 строк # . print(9999999998) print(9999999999)
Циклы же позволяют уместить такую многокилометровую запись в изящную и простую для понимания конструкцию, состоящую всего из двух строчек:
for i in range(1, 10000000000): print(i)
Смысл её крайне прост. В основе цикла for лежат последовательности, и в примере выше это последовательность чисел от 1 до 9999999999. for поэлементно её перебирает и выполняет код, который записан в теле цикла. В частности, для решения данной задачи туда была помещена инструкция, позволяющая выводить значение элемента последовательности на экран.
Итерации
- Итерация (Iteration) — это одно из повторений цикла (один шаг или один "виток" циклического процесса). К примеру цикл из 3-х повторений можно представить как 3 итерации.
- Итерируемый объект (Iterable) — объект, который можно повторять. Проще говоря это объект, который умеет отдавать по одному результату за каждую итерацию.
- Итератор (iterator) — итерируемый объект, в рамках которого реализован метод __next__, позволяющий получать следующий элемент.
�� Чтобы выполнить итерацию, Python делает следующее:
- Вызывает у итерируемого объекта метод iter() , тем самым получая итератор.
- Вызывает метод next() , чтобы получить каждый элемент от итератора.
- Когда метод next возвращает исключение StopIteration , цикл останавливается.
Пример создания итерируемого объекта Для того чтобы создать собственный класс итерируемого объекта, нужно всего лишь внутри него реализовать два метода: __iter__() и __next__() :
- внутри метода __next__ () описывается процедура возврата следующего доступного элемента;
- метод __iter__() возвращает сам объект, что даёт возможность использовать его, например, в циклах с поэлементным перебором.
Создадим простой строковый итератор, который на каждой итерации, при получении следующего элемента (т.е. символа), приводит его к верхнему регистру:
class ToUpperCase: def __init__(self, string_obj, position=0): """сохраняем строку, полученную из конструктора, в поле string_obj и задаём начальный индекс""" self.string_obj = string_obj self.position = position def __iter__(self): """ возвращаем сам объект """ return self def __next__(self): """ метод возвращает следующий элемент, но уже приведенный к верхнему регистру """ if self.position >= len(self.string_obj): # исключение StopIteration() сообщает циклу for о завершении raise StopIteration() position = self.position # инкрементируем индекс self.position += 1 # возвращаем символ в uppercase-e return self.string_obj[position].upper() low_python = "python" high_python = ToUpperCase(low_python) for ch in high_python: print(ch, end="") > PYTHON
Синтаксис for
Как было замечено, цикл for python — есть средство для перебора последовательностей. С его помощью можно совершать обход строк, списков, кортежей и описанных выше итерируемых объектов.
В простейшем случае он выглядит так:
for item in collection: # do something
Если последовательность collection состоит, скажем, из 10 элементов, for будет поочерёдно обходить их, храня значение текущего элемента в переменной item .
Принцип работы for максимально схож с таковым у циклов foreach , применяемых во многих других высокоуровневых языках.
aliceQuote = "The best way to explain it is to do it." # с помощью цикла for посчитаем количество символов (с пробелами) в строке # зададим счетчик count = 0 # будем посимвольно обходить весь текст for letter in aliceQuote: # на каждой новой итерации: # в переменной letter будет храниться следующий символ предложения; # увеличиваем счетчик на 1; count += 1 print(count) > 39
range() и enumerate()
Вы уже наверняка запомнили, что for работает с последовательностями. В программировании очень часто приходится повторять какую-то операцию фиксированное количество раз. А где упоминается "количество чего-то", существует и последовательность, числовая.
�� Для того чтобы выполнить какую-либо инструкцию строго определенное число раз, воспользуемся функцией range() :
# скажем Миру привет целых пять раз! for i in range(5): print("Hello World!") > Hello World! Hello World! Hello World! Hello World! Hello World!
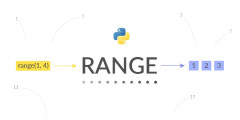
range() можно представлять, как функцию, что возвращает последовательность чисел, регулируемую количеством переданных в неё аргументов. Их может быть 1, 2 или 3:
- range(stop) ;
- range(start, stop) ;
- range(start, stop, step) .
Здесь start — это первый элемент последовательности (включительно), stop — последний (не включительно), а step — разность между следующим и предыдущим членами последовательности.
# 0 — начальный элемент по умолчанию for a in range(3): print(a) > 0 1 2 # два аргумента for b in range(7, 10): print(b) > 7 8 9 # три аргумента for c in range(0, 13, 3): print(c) > 0 3 6 9 12
�� Чрезвычайно полезная функция enumerate() определена на множестве итерируемых объектов и служит для создания кортежей на основании каждого из элементов объекта. Кортежи строятся по принципу (индекс элемента, элемент) , что бывает крайне удобно, когда помимо самих элементов требуется ещё и их индекс.
# заменим каждый пятый символ предложения, начиная с 0-го, на * text = "Это не те дроиды, которых вы ищете" new_text = "" for char in enumerate(text): if char[0] % 5 == 0: new_text += '*' else: new_text += char[1] print(new_text) > *то н* те *роид*, ко*орых*вы и*ете
break и continue
Два похожих оператора, которые можно встретить и в других языках программирования.
- break — прерывает цикл и выходит из него;
- continue — прерывает текущую итерацию и переходит к следующей.
Здесь видно, как цикл, дойдя до числа 45 и вернув истину в условном выражении, прерывается и заканчивает свою работу.
# continue for num in range(40, 51): if num == 45: continue print(num) > 40 41 42 43 44 46 47 48 49 50
В случае continue происходит похожая ситуация, только прерывается лишь одна итерация, а сам же цикл продолжается.
Если два предыдущих оператора можно часто встречать за пределами Python, то else , как составная часть цикла, куда более редкий зверь. Эта часть напрямую связана с оператором break и выполняется лишь тогда, когда выход из цикла был произведен НЕ через break .
group_of_students = [21, 18, 19, 21, 18] for age in group_of_students: if age < 18: break else: print('Всё в порядке, они совершеннолетние') > Всё в порядке, они совершеннолетние
Best practice
Цикл по списку
Перебрать list в цикле не составляет никакого труда, поскольку список — объект итерируемый:
# есть список entities_of_warp = ["Tzeench", "Slaanesh", "Khorne", "Nurgle"] # просто берём список, «загружаем» его в цикл и без всякой задней мысли делаем обход for entity in entities_of_warp: print(entity) > Tzeench Slaanesh Khorne Nurgle
Так как элементами списков могут быть другие итерируемые объекты, то стоит упомянуть и о вложенных циклах. Цикл внутри цикла вполне обыденное явление, и хоть количество уровней вложенности не имеет пределов, злоупотреблять этим не следует. Циклы свыше второго уровня вложенности крайне тяжело воспринимаются и читаются.
strange_phonebook = [ ["Alex", "Andrew", "Aya", "Azazel"], ["Barry", "Bill", "Brave", "Byanka"], ["Casey", "Chad", "Claire", "Cuddy"], ["Dana", "Ditrich", "Dmitry", "Donovan"] ] # это список списков, где каждый подсписок состоит из строк # следовательно можно (зачем-то) применить тройной for # для посимвольного чтения всех имён # и вывода их в одну строку for letter in strange_phonebook: for name in letter: for character in name: print(character, end='') > A l e x A n d r e w A y a A z a z e l B a r .
Цикл по словарю
Чуть более сложный пример связан с итерированием словарей. Обычно, при переборе словаря, нужно получать и ключ и значение. Для этого существует метод .items() , который создает представление в виде кортежа для каждого словарного элемента.
Цикл, в таком случае, будет выглядеть следующим образом:
# создадим словарь top_10_largest_lakes = # обойдём его в цикле for и посчитаем количество озер с солёной водой и количество озёр с пресной salt = 0 fresh = 0 # пара "lake, water", в данном случае, есть распакованный кортеж, где lake — ключ словаря, а water — значение. # цикл, соответственно, обходит не сам словарь, а его представление в виде пар кортежей for lake, water in top_10_largest_lakes.items(): if water == 'Freshwater': fresh += 1 else: salt += 1 print("Amount of saline lakes in top10: ", salt) print("Amount of freshwater lakes in top10: ", fresh) > Amount of saline lakes in top10: 1 > Amount of freshwater lakes in top10: 3
Цикл по строке
Строки, по сути своей — весьма простые последовательности, состоящие из символов. Поэтому обходить их в цикле тоже совсем несложно.
word = 'Alabama' for w in word: print(w, end=" ") > A l a b a m a
Как сделать цикл for с шагом
Цикл for с шагом создается при помощи уже известной нам функции range , куда, в качестве третьего по счету аргумента, нужно передать размер шага:
# выведем числа от 100 до 1000 с шагом 150 for nums in range(100, 1000, 150): print(nums) > 100 250 400 550 700 850
Обратный цикл for
Если вы еще не убедились в том, что range() полезна, то вот ещё пример: благодаря этой функции можно взять и обойти последовательность в обратном направлении.
# выведем числа от 40 до 50 по убыванию # для этого установим step -1 for nums in range(50, 39, -1): print(nums) > 50 49 48 47 46 45 44 43 42 41 40
for в одну строку
Крутая питоновская фишка, основанная на так называемых list comprehensions или, по-русски, генераторов. Их запись, быть может, несколько сложнее для понимания, зато очевидно короче и, по некоторым данным, она работает заметно быстрее на больших массивах данных.
В общем виде генератор выглядит так:
[результирующее выражение | цикл | опциональное условие]
Приведем пример, в котором продублируем каждый символ строки inputString :
# здесь letter * 2 — результирующее выражение; for letter in inputString — цикл, а необязательное условие опущено double_letter = [letter * 2 for letter in "Banana"] print(double_letter) > ['BB', 'aa', 'nn', 'aa', 'nn', 'aa']
Другой пример, но теперь уже с условием:
# создадим список, что будет состоять из четных чисел от нуля до тридцати # здесь if x % 2 == 0 — необязательное условие even_nums = [x for x in range(30) if x % 2 == 0] print(even_nums) [0, 2, 4, 6, 8, 10, 12, 14, 16, 18, 20, 22, 24, 26, 28]
Python, как подсчитать кол-во итераций в цикле for
Изучаю сортировку пузырьком для списков. Подскажите, как посчитать количество итераций в цикле for:
Всё ещё ищете ответ? Посмотрите другие вопросы с метками python или задайте свой вопрос.
Site design / logo © 2022 Stack Exchange Inc; user contributions licensed under cc by-sa. rev 2022.6.10.42345
Нажимая «Принять все файлы cookie», вы соглашаетесь, что Stack Exchange может хранить файлы cookie на вашем устройстве и раскрывать информацию в соответствии с нашей Политикой в отношении файлов cookie.