Умножение списка на число
Студент Макс узнал, что в Python умножать можно не только числа, но и другие объекты, например, строку на число:
«Вау!» — подумал Макс — «А что если умножить список на число?»:
Значит можно создать двумерный массив очень кратко и элегантно?
Макс ожидал получить:
😯 Как же так?! Дело в том, что умножение списка на число не копирует сам объект, а лишь ссылку на него. Все три элемента arr ссылаются на один и тот же список. Легко проверить, сравнив адреса объектов:
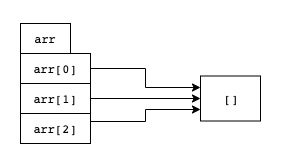
Аналогично в случае классов:
А вот с числами, строками и кортежами умножение списка будет работать как ожидал Макс, потому что это неизменяемые типы. Вот такая тонкость, которую нужно знать. Максу следовало бы написать так:
Менее кратко, но зато работает без сюрпризов: каждую итерацию создается новый пустой список.
🐉 Специально для канала @pyway. Подписывайтесь на мой канал в Телеграм @pyway 👈
Методы и способы вычисления произведения элементов списка в Python
Списки — это основная структура данных в Python, и они встречаются практически в каждом проекте. В этой статье мы рассмотрим, как вычислить произведение всех элементов списка в Python.
Простой подход: использование цикла for
Наиболее простым и понятным способом вычисления произведения всех элементов списка является использование цикла for . Вот базовый код для этого:
Использование функции reduce из модуля functools
Модуль functools в Python содержит функцию reduce() , которая позволяет применить функцию к каждому элементу списка таким образом, чтобы получить одно единственное значение. В нашем случае мы можем использовать reduce() для вычисления произведения всех элементов списка:
Обратите внимание, что мы используем operator.mul в качестве функции для reduce() . Эта функция выполняет операцию умножения.
Использование библиотеки NumPy
Если вы работаете с числовыми данными, возможно, вы уже знакомы с библиотекой NumPy . Эта библиотека предоставляет множество функций для работы с числовыми данными, включая функцию prod() , которая вычисляет произведение элементов массива:
Заключение
Вычисление произведения элементов списка является общей задачей в Python. Мы рассмотрели несколько различных подходов, включая использование цикла for , функции reduce() из модуля functools и функции prod() из библиотеки NumPy . Каждый из этих подходов имеет свои собственные преимущества и может быть наиболее подходящим в зависимости от конкретной ситуации.
Стоит также помнить о важности обработки исключений при работе с числовыми данными. В Python предусмотрено множество различных исключений, которые могут возникнуть при выполнении математических операций, и правильная их обработка позволяет избежать ошибок и неожиданного поведения программы.
Наконец, хотя этот материал фокусировался на вычислении произведения элементов списка, принципы и методы, которые мы здесь обсудили, могут быть применены и к другим агрегатным операциям. Например, вы могли бы использовать похожий подход для вычисления суммы, минимума или максимума элементов списка.
Python – math.prod() method
Math module in Python contains a number of mathematical operations, which can be performed with ease using the module. math.prod() method in Python is used to calculate the product of all the elements present in the given iterable. Most of the built-in containers in Python like list, tuple are iterables. The iterable must contain numeric value else non-numeric types may be rejected.
This method is new in Python version 3.8.
Syntax: math.prod(iterable, *, start = 1)
Parameters:
iterable: an iterable containing numeric values
start: an integer representing the start value. start is a named (keyword-only) parameter and its default value is 1.
Returns: the calculated product of all elements present in the given iterable.
itertools — Functions creating iterators for efficient looping
This module implements a number of iterator building blocks inspired by constructs from APL, Haskell, and SML. Each has been recast in a form suitable for Python.
The module standardizes a core set of fast, memory efficient tools that are useful by themselves or in combination. Together, they form an “iterator algebra” making it possible to construct specialized tools succinctly and efficiently in pure Python.
For instance, SML provides a tabulation tool: tabulate(f) which produces a sequence f(0), f(1), . . The same effect can be achieved in Python by combining map() and count() to form map(f, count()) .
These tools and their built-in counterparts also work well with the high-speed functions in the operator module. For example, the multiplication operator can be mapped across two vectors to form an efficient dot-product: sum(starmap(operator.mul, zip(vec1, vec2, strict=True))) .
Infinite iterators:
start, start+step, start+2*step, …
count(10) —> 10 11 12 13 14 .
p0, p1, … plast, p0, p1, …
cycle(‘ABCD’) —> A B C D A B C D .
elem, elem, elem, … endlessly or up to n times
repeat(10, 3) —> 10 10 10
Iterators terminating on the shortest input sequence:
accumulate([1,2,3,4,5]) —> 1 3 6 10 15
p0, p1, … plast, q0, q1, …
chain(‘ABC’, ‘DEF’) —> A B C D E F
p0, p1, … plast, q0, q1, …
chain.from_iterable([‘ABC’, ‘DEF’]) —> A B C D E F
(d[0] if s[0]), (d[1] if s[1]), …
compress(‘ABCDEF’, [1,0,1,0,1,1]) —> A C E F
seq[n], seq[n+1], starting when pred fails
dropwhile(lambda x: x<5, [1,4,6,4,1]) —> 6 4 1
elements of seq where pred(elem) is false
filterfalse(lambda x: x%2, range(10)) —> 0 2 4 6 8
sub-iterators grouped by value of key(v)
seq, [start,] stop [, step]
elements from seq[start:stop:step]
islice(‘ABCDEFG’, 2, None) —> C D E F G
pairwise(‘ABCDEFG’) —> AB BC CD DE EF FG
starmap(pow, [(2,5), (3,2), (10,3)]) —> 32 9 1000
seq[0], seq[1], until pred fails
takewhile(lambda x: x<5, [1,4,6,4,1]) —> 1 4
it1, it2, … itn splits one iterator into n
zip_longest(‘ABCD’, ‘xy’, fillvalue=’-‘) —> Ax By C- D-
Combinatoric iterators:
cartesian product, equivalent to a nested for-loop
r-length tuples, all possible orderings, no repeated elements
r-length tuples, in sorted order, no repeated elements
r-length tuples, in sorted order, with repeated elements
AA AB AC AD BA BB BC BD CA CB CC CD DA DB DC DD
AB AC AD BA BC BD CA CB CD DA DB DC
AB AC AD BC BD CD
AA AB AC AD BB BC BD CC CD DD
Itertool functions
The following module functions all construct and return iterators. Some provide streams of infinite length, so they should only be accessed by functions or loops that truncate the stream.
itertools. accumulate ( iterable [ , func , * , initial=None ] ) 
Make an iterator that returns accumulated sums, or accumulated results of other binary functions (specified via the optional func argument).
If func is supplied, it should be a function of two arguments. Elements of the input iterable may be any type that can be accepted as arguments to func. (For example, with the default operation of addition, elements may be any addable type including Decimal or Fraction .)
Usually, the number of elements output matches the input iterable. However, if the keyword argument initial is provided, the accumulation leads off with the initial value so that the output has one more element than the input iterable.
Roughly equivalent to:
There are a number of uses for the func argument. It can be set to min() for a running minimum, max() for a running maximum, or operator.mul() for a running product. Amortization tables can be built by accumulating interest and applying payments:
See functools.reduce() for a similar function that returns only the final accumulated value.
New in version 3.2.
Changed in version 3.3: Added the optional func parameter.
Changed in version 3.8: Added the optional initial parameter.
Make an iterator that returns elements from the first iterable until it is exhausted, then proceeds to the next iterable, until all of the iterables are exhausted. Used for treating consecutive sequences as a single sequence. Roughly equivalent to:
Alternate constructor for chain() . Gets chained inputs from a single iterable argument that is evaluated lazily. Roughly equivalent to:
Return r length subsequences of elements from the input iterable.
The combination tuples are emitted in lexicographic ordering according to the order of the input iterable. So, if the input iterable is sorted, the output tuples will be produced in sorted order.
Elements are treated as unique based on their position, not on their value. So if the input elements are unique, there will be no repeated values in each combination.
Roughly equivalent to:
The code for combinations() can be also expressed as a subsequence of permutations() after filtering entries where the elements are not in sorted order (according to their position in the input pool):
The number of items returned is n! / r! / (n-r)! when 0 <= r <= n or zero when r > n .
itertools. combinations_with_replacement ( iterable , r ) 
Return r length subsequences of elements from the input iterable allowing individual elements to be repeated more than once.
The combination tuples are emitted in lexicographic ordering according to the order of the input iterable. So, if the input iterable is sorted, the output tuples will be produced in sorted order.
Elements are treated as unique based on their position, not on their value. So if the input elements are unique, the generated combinations will also be unique.
Roughly equivalent to:
The code for combinations_with_replacement() can be also expressed as a subsequence of product() after filtering entries where the elements are not in sorted order (according to their position in the input pool):
The number of items returned is (n+r-1)! / r! / (n-1)! when n > 0 .
New in version 3.1.
Make an iterator that filters elements from data returning only those that have a corresponding element in selectors that evaluates to True . Stops when either the data or selectors iterables has been exhausted. Roughly equivalent to:
New in version 3.1.
Make an iterator that returns evenly spaced values starting with number start. Often used as an argument to map() to generate consecutive data points. Also, used with zip() to add sequence numbers. Roughly equivalent to:
When counting with floating point numbers, better accuracy can sometimes be achieved by substituting multiplicative code such as: (start + step * i for i in count()) .
Changed in version 3.1: Added step argument and allowed non-integer arguments.
Make an iterator returning elements from the iterable and saving a copy of each. When the iterable is exhausted, return elements from the saved copy. Repeats indefinitely. Roughly equivalent to:
Note, this member of the toolkit may require significant auxiliary storage (depending on the length of the iterable).
itertools. dropwhile ( predicate , iterable ) 
Make an iterator that drops elements from the iterable as long as the predicate is true; afterwards, returns every element. Note, the iterator does not produce any output until the predicate first becomes false, so it may have a lengthy start-up time. Roughly equivalent to:
Make an iterator that filters elements from iterable returning only those for which the predicate is false. If predicate is None , return the items that are false. Roughly equivalent to:
Make an iterator that returns consecutive keys and groups from the iterable. The key is a function computing a key value for each element. If not specified or is None , key defaults to an identity function and returns the element unchanged. Generally, the iterable needs to already be sorted on the same key function.
The operation of groupby() is similar to the uniq filter in Unix. It generates a break or new group every time the value of the key function changes (which is why it is usually necessary to have sorted the data using the same key function). That behavior differs from SQL’s GROUP BY which aggregates common elements regardless of their input order.
The returned group is itself an iterator that shares the underlying iterable with groupby() . Because the source is shared, when the groupby() object is advanced, the previous group is no longer visible. So, if that data is needed later, it should be stored as a list:
groupby() is roughly equivalent to:
Make an iterator that returns selected elements from the iterable. If start is non-zero, then elements from the iterable are skipped until start is reached. Afterward, elements are returned consecutively unless step is set higher than one which results in items being skipped. If stop is None , then iteration continues until the iterator is exhausted, if at all; otherwise, it stops at the specified position.
If start is None , then iteration starts at zero. If step is None , then the step defaults to one.
Unlike regular slicing, islice() does not support negative values for start, stop, or step. Can be used to extract related fields from data where the internal structure has been flattened (for example, a multi-line report may list a name field on every third line).
Roughly equivalent to:
Return successive overlapping pairs taken from the input iterable.
The number of 2-tuples in the output iterator will be one fewer than the number of inputs. It will be empty if the input iterable has fewer than two values.
Roughly equivalent to:
New in version 3.10.
Return successive r length permutations of elements in the iterable.
If r is not specified or is None , then r defaults to the length of the iterable and all possible full-length permutations are generated.
The permutation tuples are emitted in lexicographic order according to the order of the input iterable. So, if the input iterable is sorted, the output tuples will be produced in sorted order.
Elements are treated as unique based on their position, not on their value. So if the input elements are unique, there will be no repeated values within a permutation.
Roughly equivalent to:
The code for permutations() can be also expressed as a subsequence of product() , filtered to exclude entries with repeated elements (those from the same position in the input pool):
The number of items returned is n! / (n-r)! when 0 <= r <= n or zero when r > n .
itertools. product ( * iterables , repeat = 1 ) 
Cartesian product of input iterables.
Roughly equivalent to nested for-loops in a generator expression. For example, product(A, B) returns the same as ((x,y) for x in A for y in B) .
The nested loops cycle like an odometer with the rightmost element advancing on every iteration. This pattern creates a lexicographic ordering so that if the input’s iterables are sorted, the product tuples are emitted in sorted order.
To compute the product of an iterable with itself, specify the number of repetitions with the optional repeat keyword argument. For example, product(A, repeat=4) means the same as product(A, A, A, A) .
This function is roughly equivalent to the following code, except that the actual implementation does not build up intermediate results in memory:
Before product() runs, it completely consumes the input iterables, keeping pools of values in memory to generate the products. Accordingly, it is only useful with finite inputs.
itertools. repeat ( object [ , times ] ) 
Make an iterator that returns object over and over again. Runs indefinitely unless the times argument is specified.
Roughly equivalent to:
A common use for repeat is to supply a stream of constant values to map or zip:
Make an iterator that computes the function using arguments obtained from the iterable. Used instead of map() when argument parameters are already grouped in tuples from a single iterable (when the data has been “pre-zipped”).
The difference between map() and starmap() parallels the distinction between function(a,b) and function(*c) . Roughly equivalent to:
Make an iterator that returns elements from the iterable as long as the predicate is true. Roughly equivalent to:
Return n independent iterators from a single iterable.
The following Python code helps explain what tee does (although the actual implementation is more complex and uses only a single underlying FIFO queue):
Once a tee() has been created, the original iterable should not be used anywhere else; otherwise, the iterable could get advanced without the tee objects being informed.
tee iterators are not threadsafe. A RuntimeError may be raised when using simultaneously iterators returned by the same tee() call, even if the original iterable is threadsafe.
This itertool may require significant auxiliary storage (depending on how much temporary data needs to be stored). In general, if one iterator uses most or all of the data before another iterator starts, it is faster to use list() instead of tee() .
itertools. zip_longest ( * iterables , fillvalue = None ) 
Make an iterator that aggregates elements from each of the iterables. If the iterables are of uneven length, missing values are filled-in with fillvalue. Iteration continues until the longest iterable is exhausted. Roughly equivalent to:
If one of the iterables is potentially infinite, then the zip_longest() function should be wrapped with something that limits the number of calls (for example islice() or takewhile() ). If not specified, fillvalue defaults to None .
Itertools Recipes
This section shows recipes for creating an extended toolset using the existing itertools as building blocks.
The primary purpose of the itertools recipes is educational. The recipes show various ways of thinking about individual tools — for example, that chain.from_iterable is related to the concept of flattening. The recipes also give ideas about ways that the tools can be combined — for example, how compress() and range() can work together. The recipes also show patterns for using itertools with the operator and collections modules as well as with the built-in itertools such as map() , filter() , reversed() , and enumerate() .
A secondary purpose of the recipes is to serve as an incubator. The accumulate() , compress() , and pairwise() itertools started out as recipes. Currently, the iter_index() recipe is being tested to see whether it proves its worth.
Substantially all of these recipes and many, many others can be installed from the more-itertools project found on the Python Package Index:
Many of the recipes offer the same high performance as the underlying toolset. Superior memory performance is kept by processing elements one at a time rather than bringing the whole iterable into memory all at once. Code volume is kept small by linking the tools together in a functional style which helps eliminate temporary variables. High speed is retained by preferring “vectorized” building blocks over the use of for-loops and generator s which incur interpreter overhead.